
Promoted
Greater Accra, Accra Metropolitan, 1 day ago
2 views
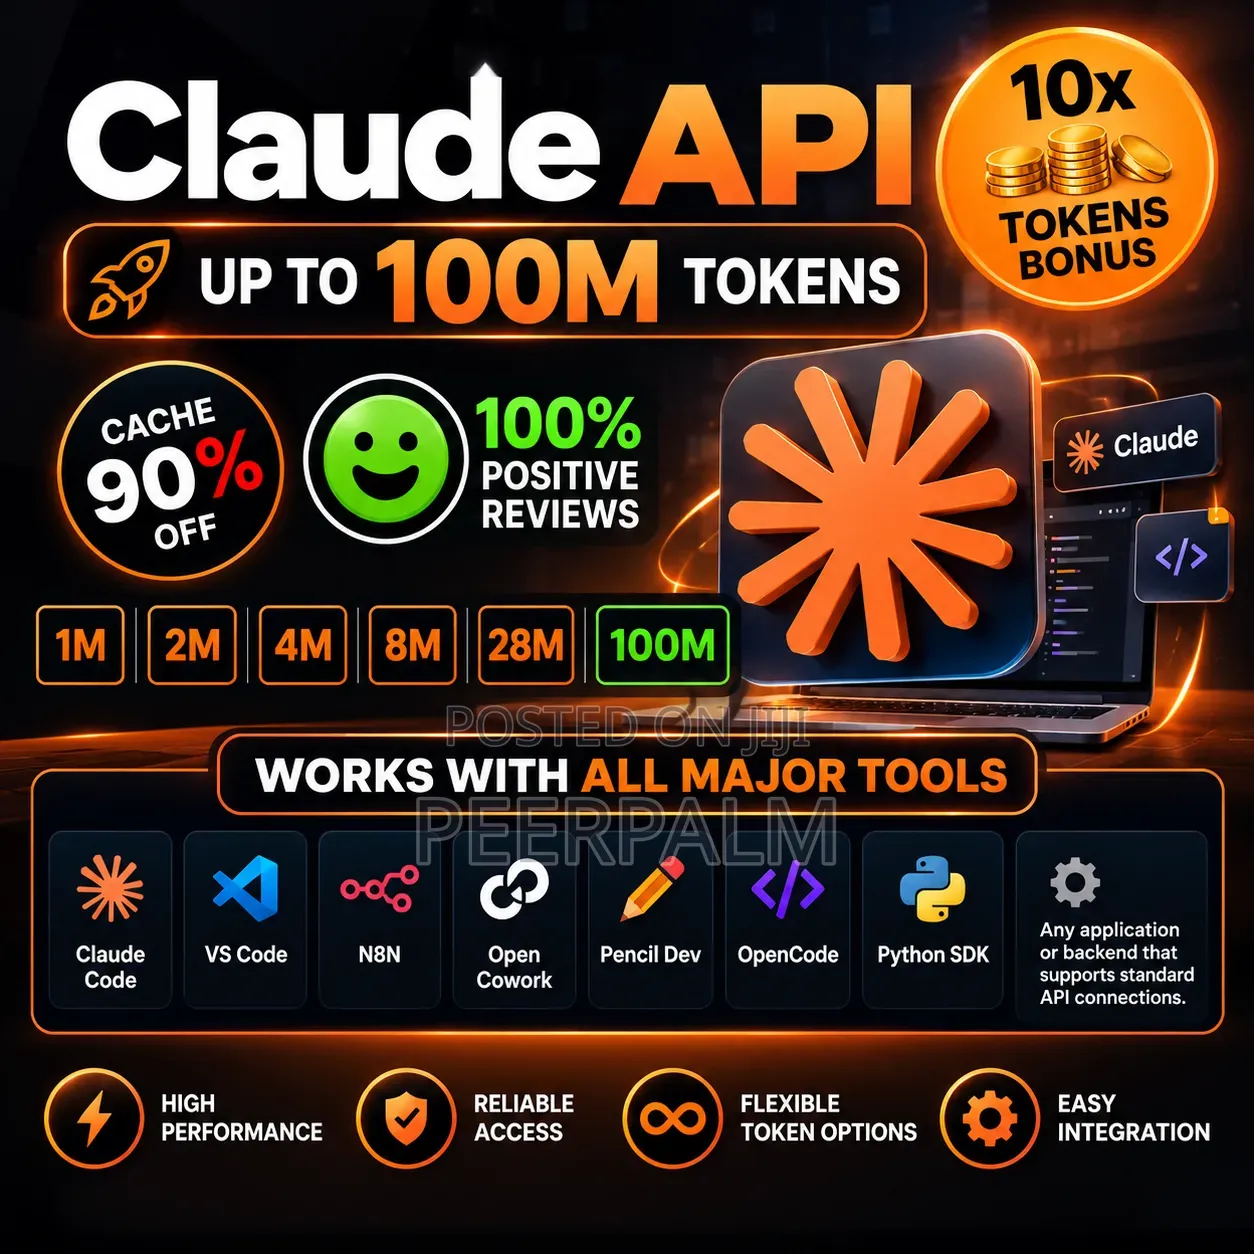
Claude Api 2m | Fable 5.1 Opus 5 | Claude Code
Claude API
Software Name
Other
Type
Windows
Platform
Email
Format
Lifetime
License Duration
We use cache read (covering 90% of your work), which means you spend 10 times fewer tokens overall!
immediately after payment, you receive:
— api key
— base url
— link to your personal dashboard
other packages: 4m / 8m / 15m / 25m / 50m / 100m
works with all major tools
claude code, vs code, n8n, open cowork, pencil dev, opencode, python sdk, and any application or backend that supports standard api connections.
important: prompt-cache savings
cached tokens are charged 90% cheaper
as a result, the package or balance provides approximately 5–6 times more total usage.
frequently asked questions
are there any speed limits?
up to 120 requests per minute per api key. actual response speed depends on the selected model, context size, and current load.
GH₵ 6
Fixed price
Safety tips
- Avoid paying in advance, even for delivery
- Meet with the seller at a safe public place
- Inspect the item and ensure it's exactly what you want
- Make sure that the packed item is the one you've inspected
- Only pay if you're satisfied


